


 Sign In


Machine learning transforms how businesses solve problems, from predicting customer churn to detecting fraud. Yet for beginners, the journey from curiosity to competency feels overwhelming. You encounter unfamiliar terminology, struggle to understand which algorithms to use, and wonder how to turn raw data into actionable insights.
This guide eliminates that confusion. We’ll walk through the complete machine learning workflow using Python and scikit-learn, the most practical toolkit for applied machine learning. By the end, you’ll not only understand machine learning concepts but build working models that make accurate predictions.
Why Python and Scikit-learn for Machine Learning Mastery?
Python has become the de facto standard for machine learning development. Its simplicity, vast ecosystem, and production-ready capabilities make it ideal for both learning and deployment. Within Python’s ecosystem, scikit-learn stands out as the essential library for practical machine learning.
Scikit-learn eliminates the complexity of implementing algorithms from scratch. Instead of spending weeks on mathematical implementations, you focus on the real challenge: understanding your data and choosing the right approach. It integrates seamlessly with other Python libraries like pandas for data handling and matplotlib for visualization.
The combination of Python and scikit-learn creates a learning path that’s immediately relevant. Code you write in tutorials scales directly to production environments. This contrasts with theoretical approaches that require complete rewrites when building real systems.
Understanding the Machine Learning Fundamentals
Before diving into code, grasp the core concepts underlying every machine learning project. Machine learning teaches computers to learn from data without explicit programming. Instead of following predetermined rules, machine learning systems discover patterns and relationships in data, then use those patterns to make predictions on new, unseen information.
Three main categories organize machine learning problems. Supervised learning requires labeled data, where you know the correct answer. You train algorithms to predict house prices based on historical sales data, for example. The algorithm learns the relationship between features (square footage, location, age) and the target (price).
Unsupervised learning finds hidden patterns in unlabeled data. You might cluster customers by purchasing behavior without predefined categories, discovering natural groupings the business never knew existed. This approach excels at exploratory analysis and data understanding.
Reinforcement learning involves an agent learning through interaction and rewards. While powerful for games and robotics, it’s less common in business applications for beginners, so we’ll focus on supervised and unsupervised approaches.
The Machine Learning Workflow: A Step-by-Step Framework
Successful machine learning mastery requires following a proven workflow. This framework applies to nearly every project, from your first personal project to enterprise applications.
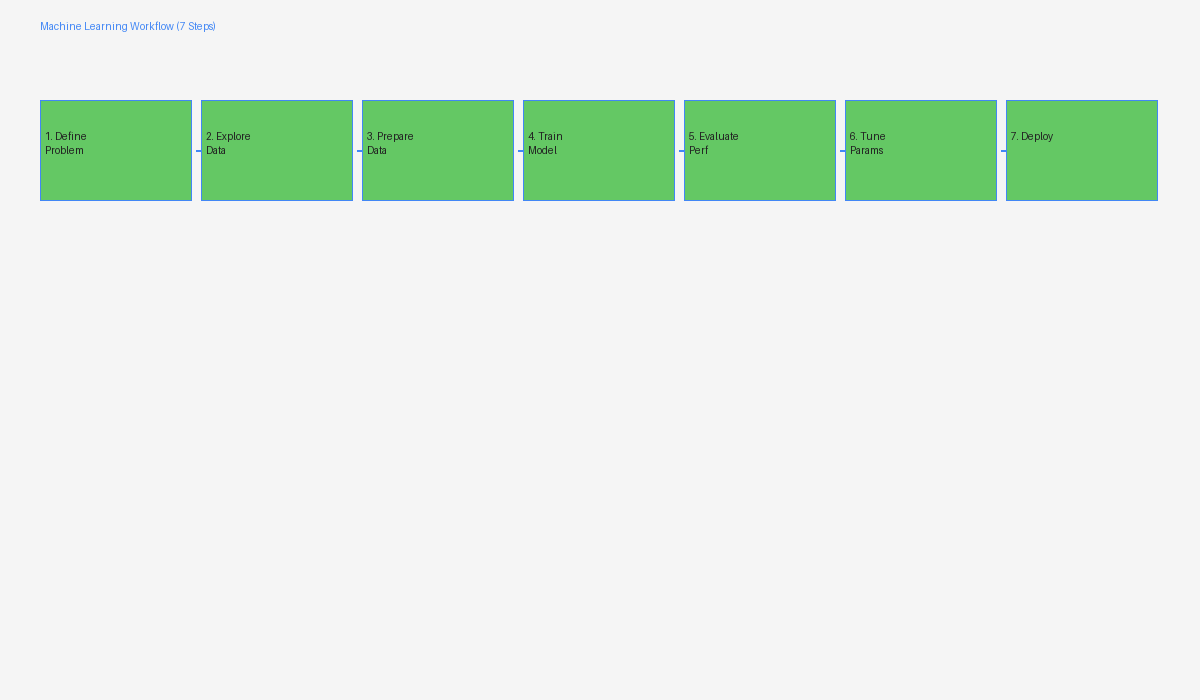
Step 1: Define Your Problem and Gather Data
Every machine learning project starts with a clear business question. Instead of “build a machine learning model,” ask specific questions: “Can we predict customer churn 30 days in advance?” or “What features drive product recommendations?”
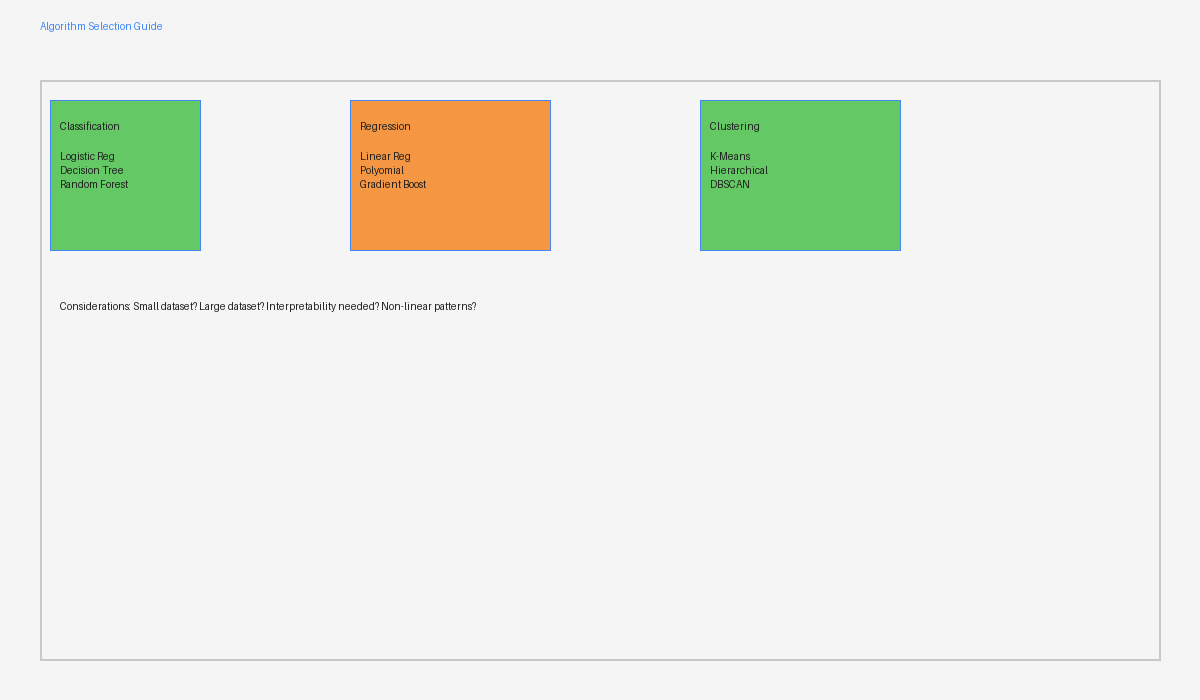
Your question determines your data requirements and the type of machine learning approach. Classification problems predict categories (will churn: yes/no). Regression problems predict continuous values (expected revenue next quarter). This distinction shapes your entire approach.
Data gathering requires more effort than most beginners expect. You’ll spend considerable time locating, accessing, and aggregating data from multiple sources. Quality data drives quality models. A mediocre algorithm on excellent data outperforms an sophisticated algorithm on poor data every time.
Step 2: Explore and Understand Your Data
This phase, called exploratory data analysis (EDA), reveals patterns, distributions, and anomalies in your data. It’s where you truly understand what you’re working with before attempting any machine learning modeling.
Use descriptive statistics to understand your variables. What’s the average customer age? How much variation exists? Are most values clustered around a central point or widely spread? Visualizations make patterns immediately apparent. A histogram shows value distributions. Scatter plots reveal relationships between variables. Correlation matrices identify which features move together.
During exploration, you’ll identify missing values, outliers, and data quality issues. These discoveries guide your next decisions. Do you remove rows with missing values or estimate them? Are extreme values measurement errors or genuine edge cases? This exploration step directly influences model performance.
Step 3: Prepare Data for Machine Learning Algorithms
Raw data rarely works with machine learning algorithms. Data preparation transforms messy real-world information into a format algorithms can process effectively.
Handling missing values requires care. Simple deletion works only when you have abundant data. For sparse datasets, you might estimate missing values using the mean, median, or more sophisticated methods. Sometimes, “missing” itself contains information, deserving its own indicator variable.
Feature scaling ensures all variables contribute fairly to model training. Algorithms sensitive to magnitude (like K-nearest neighbors) treat age (0-100) and income (0-1,000,000) differently. Standardizing features to a common scale prevents one variable from dominating due to its larger magnitude.
Categorical variables require encoding before algorithms can process them. Color (red, blue, green) has no inherent numerical order. One-hot encoding creates binary columns for each category. Target encoding replaces categories with statistical summaries. The choice depends on your specific algorithm and data characteristics.
Step 4: Select and Train Your Model
Scikit-learn provides dozens of algorithms. Beginners often struggle choosing among them. The answer depends on your problem type and data characteristics.
For classification problems, start with logistic regression despite its name. It’s simple, interpretable, and surprisingly effective. If performance falls short, try decision trees or random forests. Support vector machines excel with smaller datasets. Neural networks dominate with massive datasets.
For regression problems, begin with linear regression. Explore polynomial regression if relationships appear nonlinear. Random forests and gradient boosting handle complex patterns without extensive feature engineering.
Step 5: Evaluate Model Performance
Training accuracy is a trap. A model might memorize training data perfectly yet fail miserably on new examples. This overfitting occurs when models learn noise rather than underlying patterns.
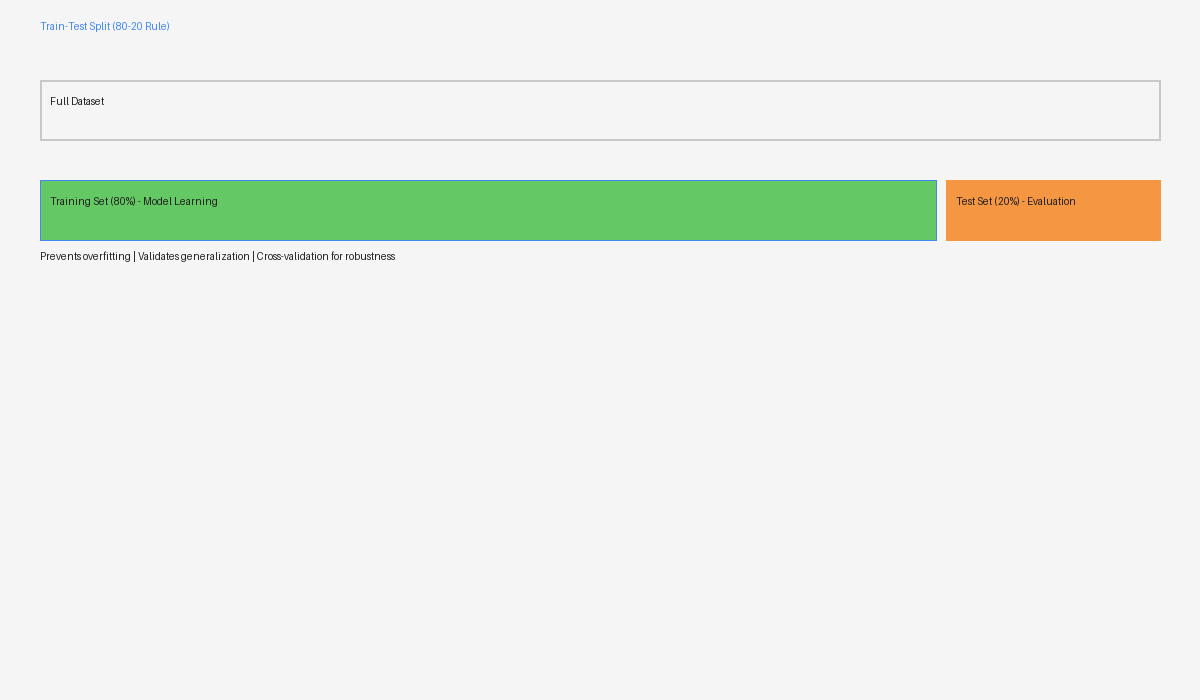
Proper evaluation requires train-test splits. Train your model on a subset of data, then evaluate on unseen data. If train accuracy is 95% but test accuracy is 70%, overfitting is occurring.
For classification, accuracy measures correct predictions as a percentage. But with imbalanced data, accuracy misleads. If 95% of examples are negative, a model predicting “negative” always achieves 95% accuracy while being useless. Precision measures correct positive predictions among all positive predictions. Recall captures correct positive predictions among all actual positives. F1-score balances precision and recall.
For regression, mean squared error penalizes large errors. Mean absolute error expresses errors in original units. R-squared indicates what percentage of variance your model explains. Cross-validation strengthens evaluation. Instead of single train-test splits, divide data into multiple folds, train multiple models, and average results. This approach better estimates real-world performance.
Step 6: Tune and Optimize Your Model
Initial models rarely represent your best work. Hyperparameters—settings that control algorithm behavior—dramatically affect performance.
Decision trees have maximum depth and minimum samples requirements. Neural networks have learning rates and layer sizes. Random forests have the number of trees and features per split. Finding optimal values requires systematic experimentation.
Grid search tests combinations of hyperparameters systematically. Specify ranges for each hyperparameter, and grid search tests all combinations, reporting the best-performing set. Random search samples combinations randomly, useful when hyperparameter spaces are large.
Step 7: Deploy and Monitor Your Model
Once your model achieves acceptable performance, deployment makes it useful. This varies from exporting a scikit-learn model for batch predictions to deploying an API serving real-time predictions.
Real-world performance diverges from development performance. Models trained on historical data face new patterns in production. Regular monitoring catches performance degradation, triggering retraining. This continuous cycle maintains model relevance.
Building Your First Machine Learning Model: A Hands-On Example
Let’s apply this framework to a concrete example. We’ll predict whether a customer will purchase an insurance product based on demographic and behavioral features.
1. Import Libraries and Load Data
import pandas as pd import numpy as np from sklearn.model_selection import train_test_split from sklearn.preprocessing import StandardScaler from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score, precision_score, recall_score, f1_score data = pd.read_csv(‘insurance_customers.csv’) print(data.head()) print(data.info()) print(data.describe())
This opens the data and provides initial insights into structure and statistics.
2. Prepare Features and Target
X = data.drop(‘purchased_insurance’, axis=1) y = data[‘purchased_insurance’] X = pd.get_dummies(X, columns=[‘region’, ‘job_type’], drop_first=True) X.fillna(X.mean(), inplace=True)
This transformation makes data suitable for algorithm consumption.
Common Pitfalls and How to Avoid Them
Pitfall 1: Data Leakage
Data leakage means information from outside the training set influences model training. For example, using future information to predict the present, or preprocessing your entire dataset before splitting.
Always split data before preprocessing. Fit scalers, encoders, and imputers only on training data. Apply these transformations to test data. This prevents future information from leaking backward.
Pitfall 2: Ignoring Class Imbalance
When your target variable has unequal class distributions (90% negative examples, 10% positive), accuracy misleads. A naive model predicting “negative” always achieves 90% accuracy despite being useless.
Address imbalance through resampling (oversampling minorities, undersampling majorities) or algorithm adjustments (class weights). Evaluate using precision, recall, and F1-score rather than accuracy alone.
Pitfall 3: Inadequate Hyperparameter Tuning
Default hyperparameters rarely produce optimal results. Yet many beginners train one model with defaults and declare victory.
Use grid search or random search to explore hyperparameter combinations. Combine this with cross-validation for robust estimates. Spend significant time here—this often yields larger improvements than algorithm selection.
Pitfall 4: Overfitting Through Excessive Feature Engineering
Creating too many features relative to training examples causes overfitting. The model learns noise rather than signal.
Start simple. Use domain expertise to create meaningful features. Remove highly correlated features. Regularization techniques (L1/L2) penalize complexity. Monitor test performance carefully.

Pitfall 5: Neglecting Production Considerations
Models built in notebooks often fail in production. Latency requirements, computational resources, explainability needs, and monitoring infrastructure get overlooked.
Plan for production early. Consider inference speed, model size, and whether business stakeholders can understand predictions. Build monitoring from day one.
Practical Machine Learning Projects for Beginners
Theoretical knowledge means little without practical application. Build these projects to solidify your understanding.
Project 1: Iris Classification
Use the famous Iris dataset to classify flowers into species based on measurements. This classic beginner project has clean data and clear patterns. Practice loading data, exploratory analysis, training multiple algorithms, and comparing performance.
Project 2: Housing Price Prediction
Predict house prices from features like square footage, bedrooms, and location. This regression problem teaches feature engineering and reveals how domain knowledge improves models. Explore nonlinear relationships and interaction effects.
Project 3: Titanic Survival Prediction
Predict whether Titanic passengers survived based on age, class, and gender. This binary classification handles missing values and categorical features realistically. It forces engagement with data quality issues encountered in real projects.
Project 4: Customer Churn Analysis
Predict which customers will leave your service. This business-relevant problem teaches imbalanced classification, temporal thinking, and translating predictions to business actions.
Project 5: Sentiment Analysis on Review Data
Classify product reviews as positive or negative. This natural language processing introduction handles text data, requiring different preprocessing approaches than numerical features.

Advanced Topics to Explore After Mastering Fundamentals
Once comfortable with basic machine learning workflows, explore advanced topics that distinguish expert practitioners from novices.
Feature Selection and Dimensionality Reduction
With thousands of features, not all contribute meaningfully. Feature selection identifies the most important variables. Principal component analysis reduces dimensions while preserving information. These techniques improve model interpretability and computational efficiency.
Ensemble Methods
Combining multiple models often outperforms individual models. Bagging trains multiple models on random subsets and averages predictions. Boosting trains models sequentially, each correcting previous errors. Stacking uses meta-learners combining base model predictions.
Continue Your Machine Learning Journey

This guide provides the comprehensive framework for machine learning success. The knowledge you’ve gained here applies to real-world problems you’ll encounter throughout your career. The fundamentals endure even as new algorithms and frameworks emerge.
Ready to dive deeper with structured, hands-on learning?
Explore Machine Learning Mastery: A Beginner’s Guide with Python & Scikit-learn for comprehensive tutorials built on these fundamentals, interactive projects, and real-world applications that accelerate your path to mastery.
Your competitive advantage in machine learning comes not from following tutorials passively but from engaging actively with real data and real problems. Begin today. Choose a project that matters to you. Build your first meaningful model. That moment when predictions align with reality justifies the effort.
Now is the time to start your machine learning mastery journey.


